VoiceNotes
Privacy-first voice intelligence platform. Local-first tri-surface architecture (120Hz Expo Android app, Next.js 16 Neural Dashboard, Dockerized FastAPI backend), 4-field intent router RAG gate, faster-whisper, and Ollama-served LLMs running end-to-end with zero cloud dependencies.
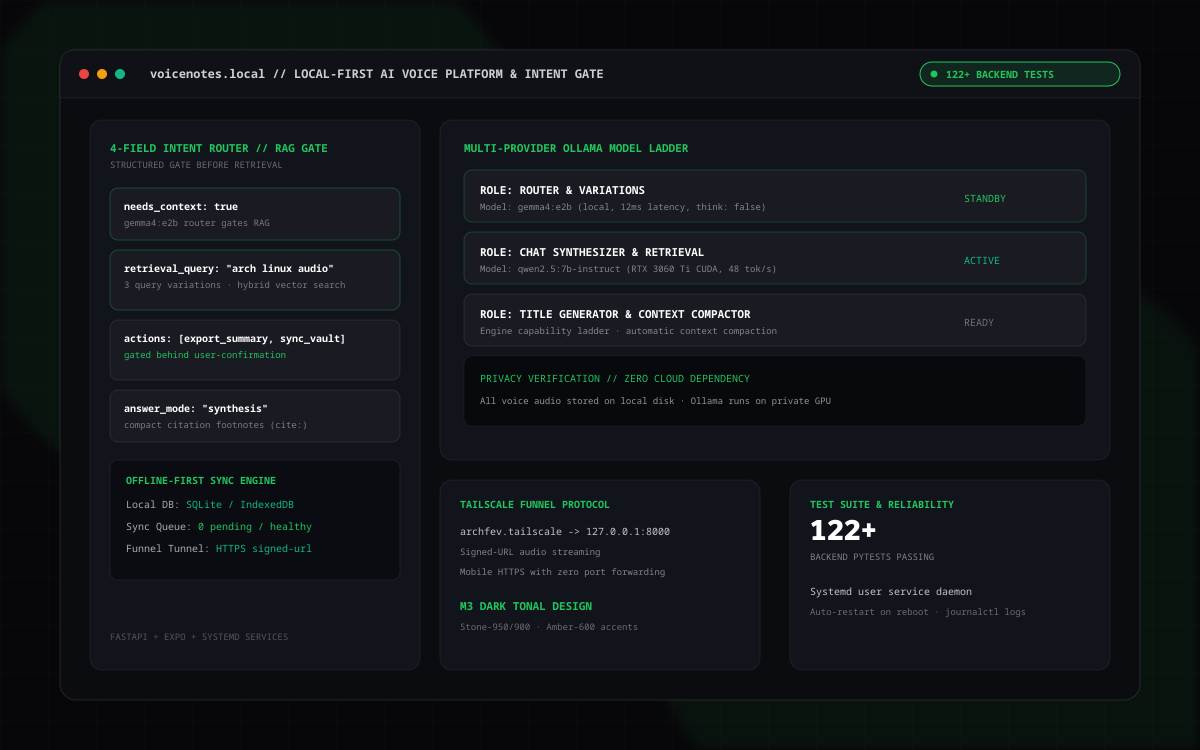
Voice recordings represent deeply intimate personal data.
Voice recordings represent deeply intimate personal data. Commercial voice assistants upload audio and transcripts to cloud datacenters, creating privacy exposure and failing when offline. The architecture required complete local-first isolation: transcription, semantic embedding, LLM reasoning, and audio storage running entirely on private consumer hardware with zero cloud dependencies, backed by robust offline sync and multi-device streaming.
Engineered a local-first tri-surface architecture: built a native Android Expo companion (React Native / Reanimated 4 at 120Hz), a Next.js 16 Neural Dashboard, and a Dockerized FastAPI backend serving local Ollama models (gemma4:e4b / e2b) and faster-whisper with zero cloud deps.
Designed a 4-field structured intent router: analyzes queries across needs_context, retrieval_query, actions, and answer_mode to gate RAG retrieval, prevent hallucinated citations on action requests, and enforce a client-side confirmation gate before creating notes.
Implemented multi-query hybrid search with Reciprocal Rank Fusion (RRF): combines pgvector semantic embeddings (nomic-embed-text) and PostgreSQL full-text search (tsvector) with citation verification ensuring only genuinely referenced notes attach to chat history.
Built an engine capability ladder & adaptive context compaction: dynamically discovers model token limits, routes specialized roles (router, judge, summarizer, note intelligence), compacts active sessions at 75% limit, and streams signed audio over Tailscale Funnel (HTTPS).